SERVICES
Portfolio » Full-Stack Enterprise Web Application with Microservices » CogniFlow: AI-Powered Semantic Enterprise Search & Intelligence Platform
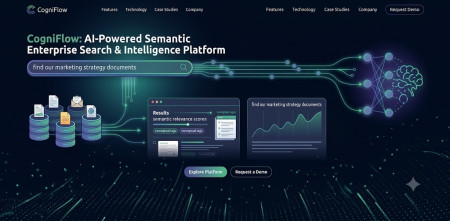
CogniFlow: AI-Powered Semantic Enterprise Search & Intelligence Platform
Technologies Used:
Used: Python, Hugging Face Transformers (BERT, RoBERTa), FastAPI, Pinecone Vector Database, spaCy, LangChain, React (FroProject Type:
Full-Stack Enterprise Web Application with MicroservicesProject Description:
Modern enterprises are drowning in data, most of it unstructured in the form of documents, emails, reports, and other text-based content. Information is often siloed across diverse repositories, making effective search a nearly impossible task. Traditional keyword-based search systems fall short because they only match exact words, missing the conceptual meaning behind a user's query. This leads to massive time waste for employees searching for relevant content, duplicated work, and a general loss of organizational knowledge and productivity. CogniFlow was designed as a full-stack, enterprise-grade solution to address this challenge by leveraging state-of-the-art Natural Language Processing (NLP) techniques to provide semantic search, intelligent categorization, and automatic summarization.
The core of CogniFlow is a sophisticated NLP pipeline. It begins with text ingestion, where raw data is collected from internal company data sources. During preprocessing, spaCy is used for advanced text cleaning, tokenization, and named entity recognition (NER) to structure the data and identify key entities (e.g., people, organizations, dates). The central intelligence relies on Transformer models—specifically, we fine-tuned variations of BERT and RoBERTa via the Hugging Face library on domain-specific datasets. These models generate high-dimensional vector representations (embeddings) that capture the deep semantic meaning of documents and paragraphs.
For efficient retrieval, these embeddings are stored in Pinecone, a cloud-native vector database optimized for approximate nearest neighbor search. When a user submits a natural language query, it is also embedded into a vector, and Pinecone quickly retrieves the most semantically relevant documents. Our system includes a custom reranking module that refines these results based on additional factors like metadata and user relevance feedback. Beyond pure search, CogniFlow provides an intuitive
dashboard for interactive knowledge discovery. Documents are automatically categorized using hierarchical classification models, and users can generate concise, high-quality summaries of long reports with a single click, powered by models like T5 for summarization. The entire backend is built with Python's FastAPI framework as a suite of Dockerized microservices, ensuring scalability, reliability, and easy integration. The modern frontend is built with React, offering a polished interface with complex data visualizations
and an interactive search experience.
In deployment at an early client, a global consulting firm, CogniFlow demonstrated a 40% reduction in average search time, a significant improvement in the discovery of relevant documents, and a measurable increase in general knowledge utilization. It transformed a fragmented and inefficient process into a streamlined enterprise intelligence engine, enabling faster decision-making and better strategic alignment across teams.